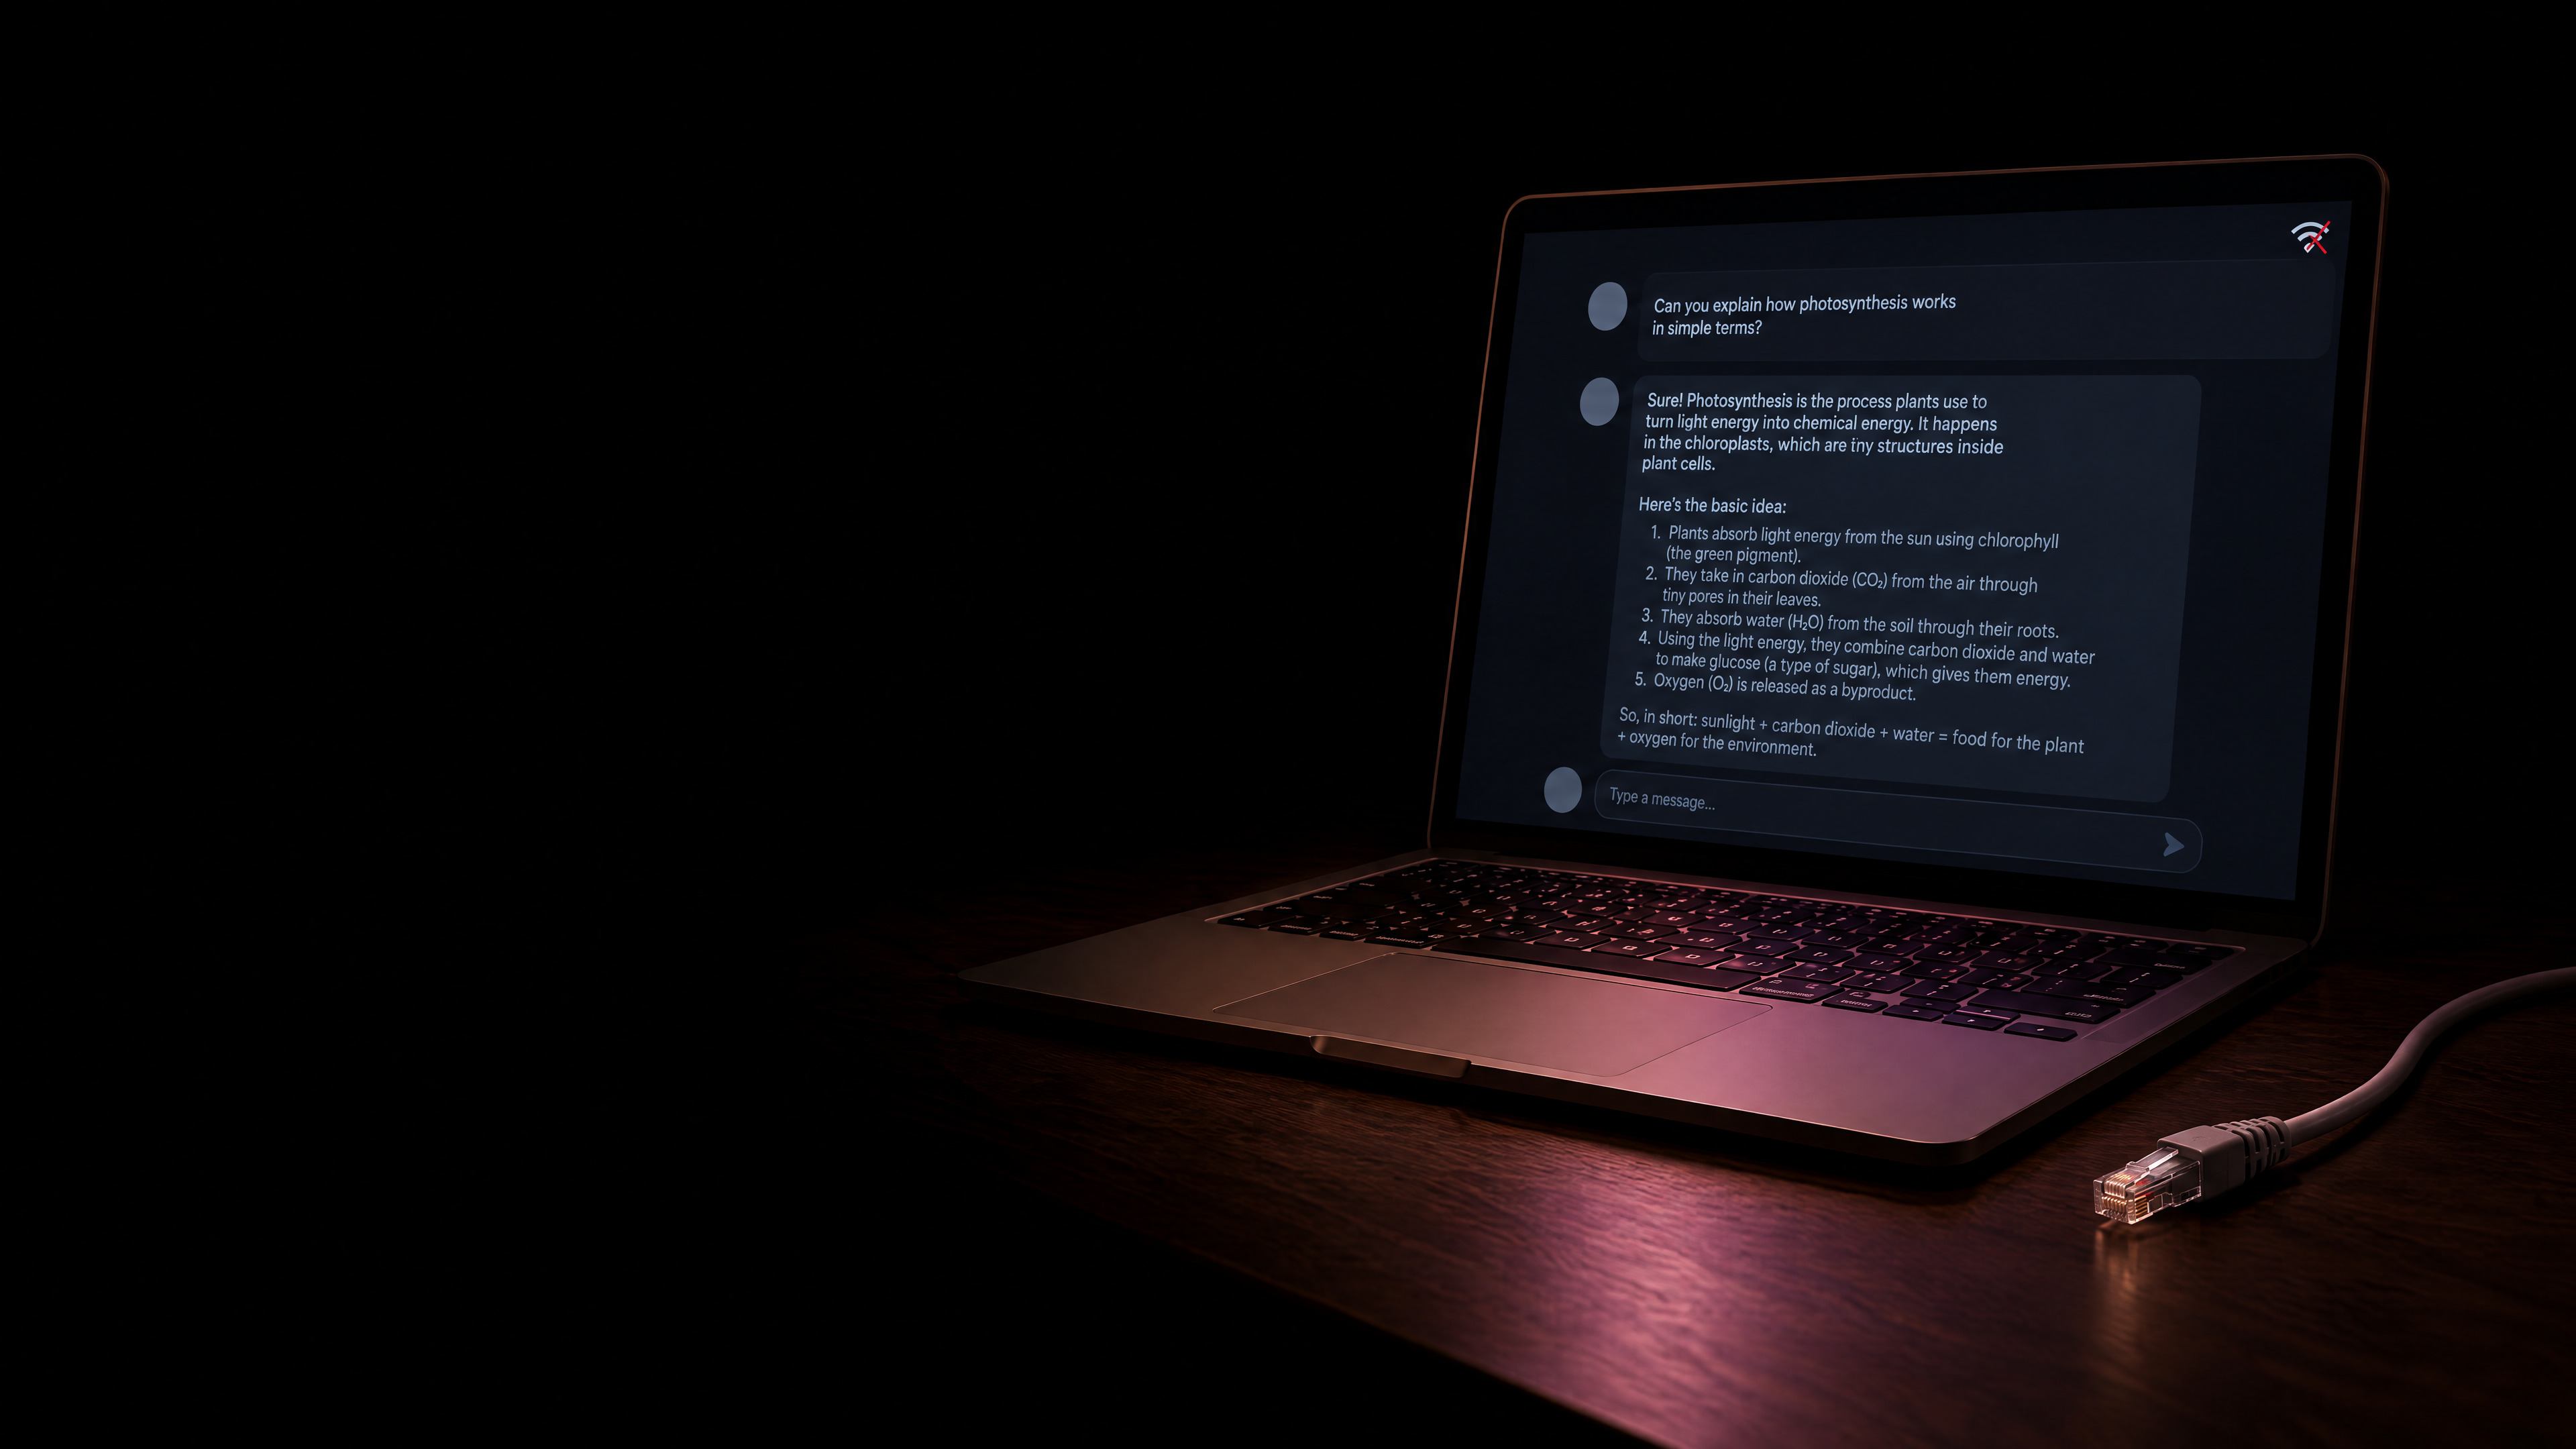
no internet,
and it still
answers.
image: ai-generated (gpt-image-2.5-flare)
when you chat with ChatGPT, where does the model run?
  1. on my phone or laptop
  2. in my browser
  3. in a data centre
  4. no idea
how big is a language model that runs on a laptop?
  1. a few megabytes
  2. one to a few gigabytes
  3. around 100 gigabytes
  4. no idea

step 1 · switch it off

turn off wi-fi.
load gemma 3 1b in LM Studio.
ask it: “what does nitrogen fertiliser do for a wheat plant? two sentences.”

step 2 · find the file

LM Studio → my models → show in folder.
how big is the file, and what is it called?

step 3 · three questions, two models

a field of 4.5 ha needs 140 kg of nitrogen per ha. how much is that in total?
what is the capital of lower saxony, and what is it known for?
translate into german: “the harvest was delayed by rain.”
ask gemma 3 1b first, then gemma 3 4b, and note the tokens per second below each answer.
how many tokens per second did gemma 3 4b reach on your laptop?
  1. fewer than 5
  2. 5 to 20
  3. 20 to 50
  4. more than 50

1b or 4b?

gemma 3 1b
gemma 3 4b
file
0.75 GB
2.4 GB
speed
your tokens/s?
your tokens/s?
quality
which answers held?
which answers held?
if a model like GPT-6.1 Sol lay on your laptop, how big would the file be?
  1. about 5 gigabytes
  2. about 50 gigabytes
  3. about 500 gigabytes
  4. several terabytes

a file full of numbers

how many values fit into a few bits?

1 bit
→
2 values
2 bits
→
4 values
4 bits
→
16 values
16 bits
→
65,536 values
every extra bit doubles the number of values a weight can take.

rounding one weight

simplified: 16 evenly spaced values between −1 and +1

four weights, rounded

16 bits
4 bits
3 values
binary
0.0213
0.067 1000
0
1
−0.7744
−0.733 0010
−1
−1
0.3301
0.333 1010
0
1
0.8711
0.867 1110
1
1
the coarser the rounding, the smaller the file, and the further the model drifts from what it learned.

why 2.4 GB?

4 billion numbers × 16 bits = 8 GB
4 billion numbers × ~4.5 bits = 2.4 GB
fewer bits per number: quantization.

rounding costs less than shrinking

what happens when you press enter

bigger models are slower, because every token passes through more numbers.

how big is big?

parameters as published by the providers; log scale

local and cloud

the same harness can talk to a model on your laptop.
see also: the harness

open weights, closed weights

open
download it, run it, change it.
gemma, qwen, llama, mistral, deepseek, gpt-oss
closed
use it as a service.
gpt, claude, gemini
open weights is not the same as open source: the training data usually stays secret.
would you paste a farm's customer list into a cloud chatbot?
  1. yes
  2. only with a contract
  3. only into a local model
  4. never

when local makes sense

your data must not leave the building.
you need it offline, in a barn, on a tractor or on your phone.
you use it so much that tokens get expensive.
and you accept a smaller, slower model in return.
on a phone: google ai edge gallery, an app that runs small gemma models offline on android and ios

key takeaway

a language model is a file full of numbers that runs on your own laptop without the internet; its size decides how good, how fast and how hungry it is.

discuss

what surprised you about the size, speed or quality of the local model?
which data would you trust a local model with, but not a cloud service?
when should a farm or a food company run its own model instead of renting one?